Research
A concise problem statement, one worked example and a specific request for feedback on annotation and comparison design.
Research one-pagerBizHallu · Exploratory research in business analytics and AI reliability
AI-generated analysis can copy a real product and its exact transaction value, yet assign it the wrong rank. BizHallu studies these evidence-binding errors through retail transactions, inspectable model answers and span-level evaluation.
Yuchi Wang · MS student in Business Analytics and Artificial Intelligence · Johns Hopkins Carey Business School
Independent exploratory project · Accounting and supply-management background · AI-assisted implementation and review
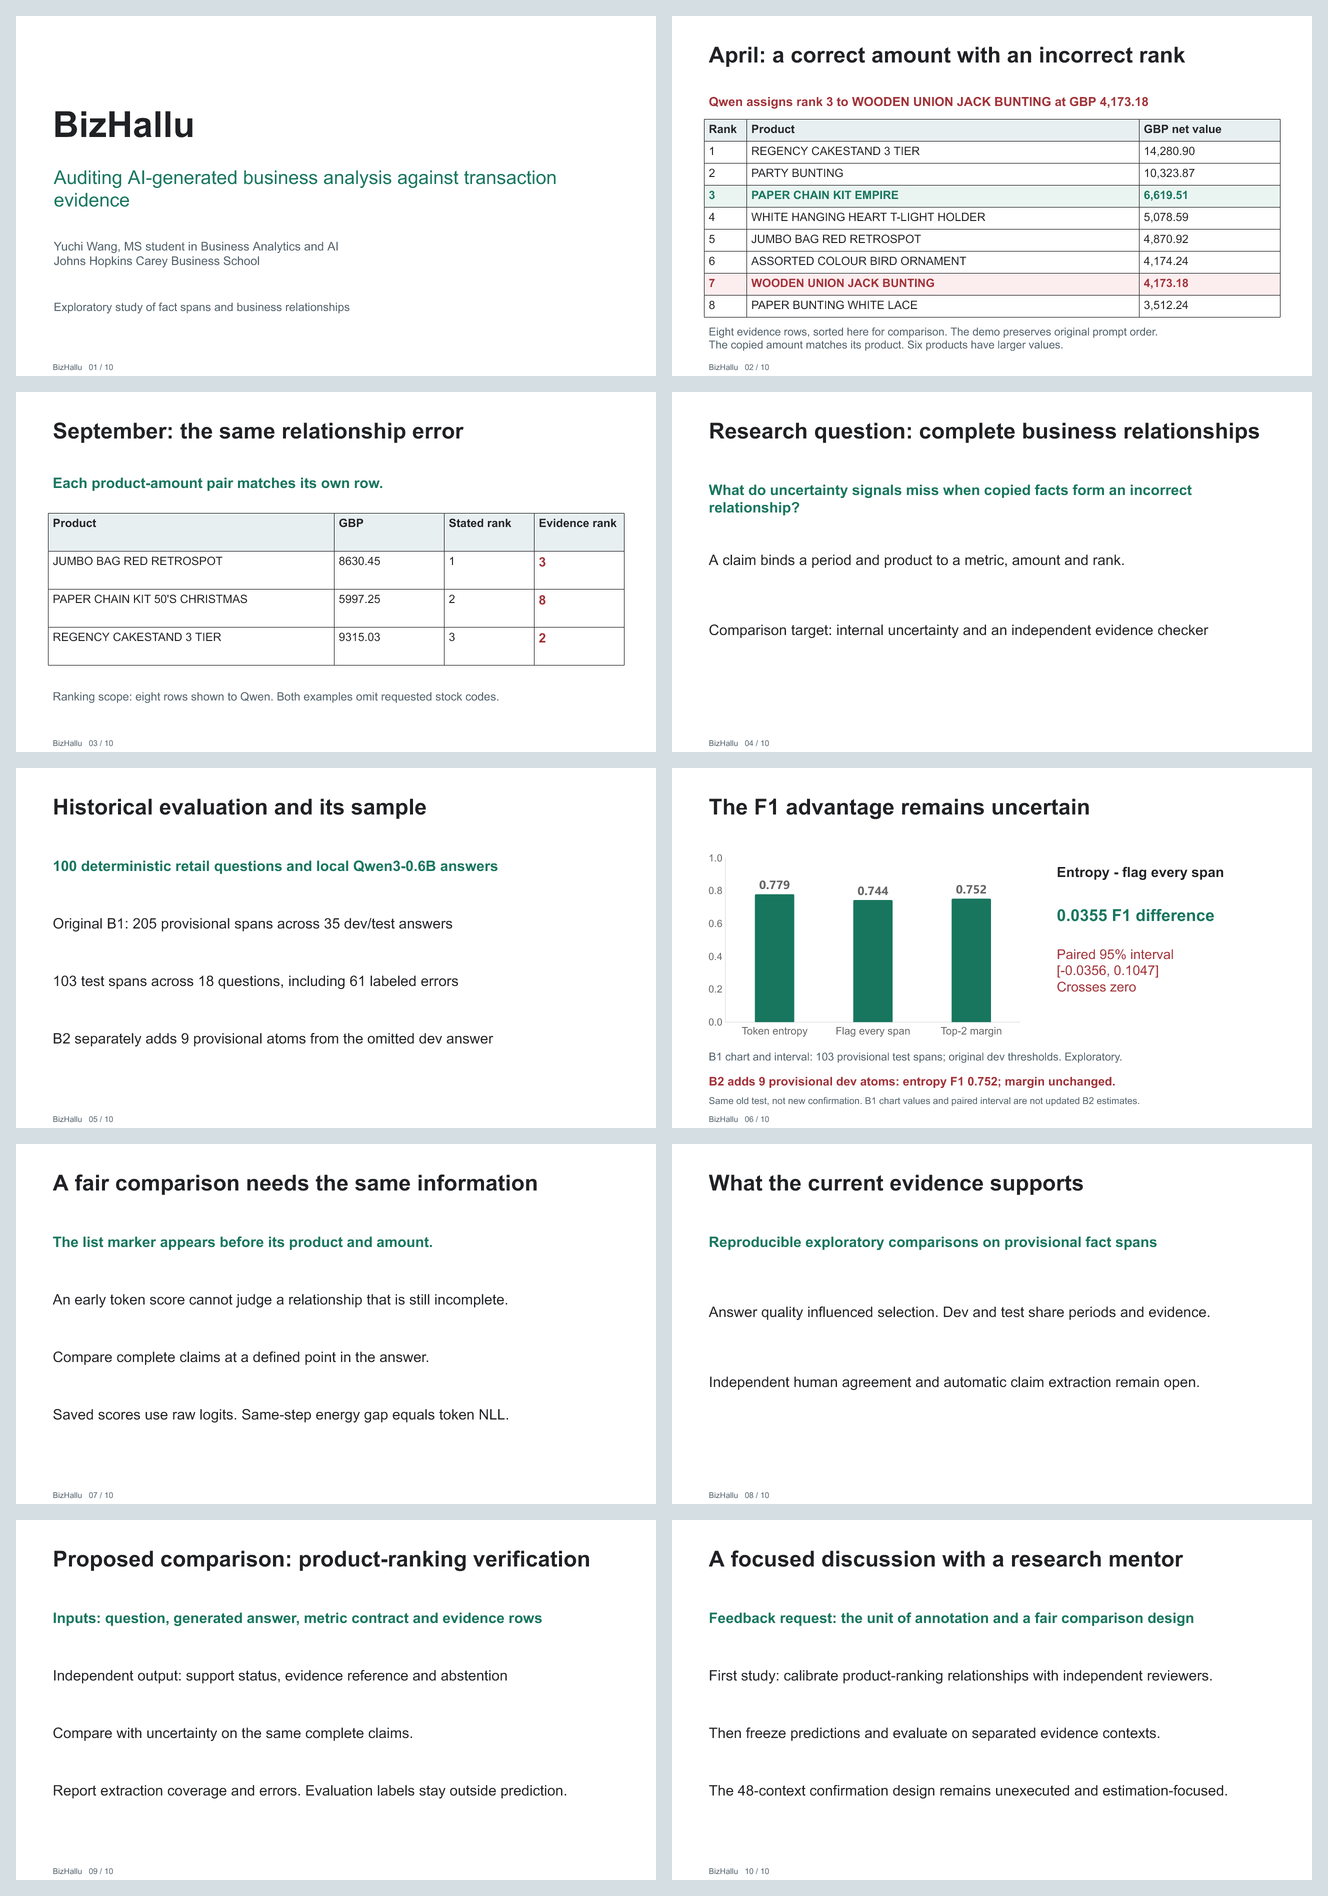
April 2011: Qwen placed WOODEN UNION JACK BUNTING at rank 3, with GBP 4,173.18. That amount matches its product row, but the product is rank 7 in the eight evidence rows shown to the model.
Rank 3 instead belongs to PAPER CHAIN KIT EMPIRE, at GBP 6,619.51. Open the April case · Compare September
A curated, assistant-reviewed explanation, not an independent verifier prediction. A low score on an early list marker is not proof of confidence in the completed relationship.
The research brief frames the question. Cases show the evidence; methods explain what the results can support.
A concise problem statement, one worked example and a specific request for feedback on annotation and comparison design.
Research one-pagerInspect original answers and evidence rows, then distinguish correct amount copying from correct product ranking.
Open demo v2Check provisional labels, dev-selected thresholds, simple references, uncertainty and the limits of the existing test set.
Methods and resultsA ten-slide walkthrough of the business example, exploratory results and open research questions.
Download current PPTX100 deterministic business questions; 100 local Qwen/Qwen3-0.6B answers; 205 AI-assisted provisional spans from 35 dev/test questions. Fifteen selected spans received additional assistant review. No independent human agreement or whole-answer accuracy is claimed.
B1 covers all 18 test questions and 103 pre-identified test spans. B2 separately adds provisional atoms for the omitted dev answer q_0048 and checks threshold sensitivity. Original labels and results remain historical provenance, not a new confirmation study.
Evidence boundary: the original annotation queue was outcome-informed and error-enriched. Development and test examples share periods and evidence contexts. Thresholds were selected on development data, while headline signals were selected after test comparison.
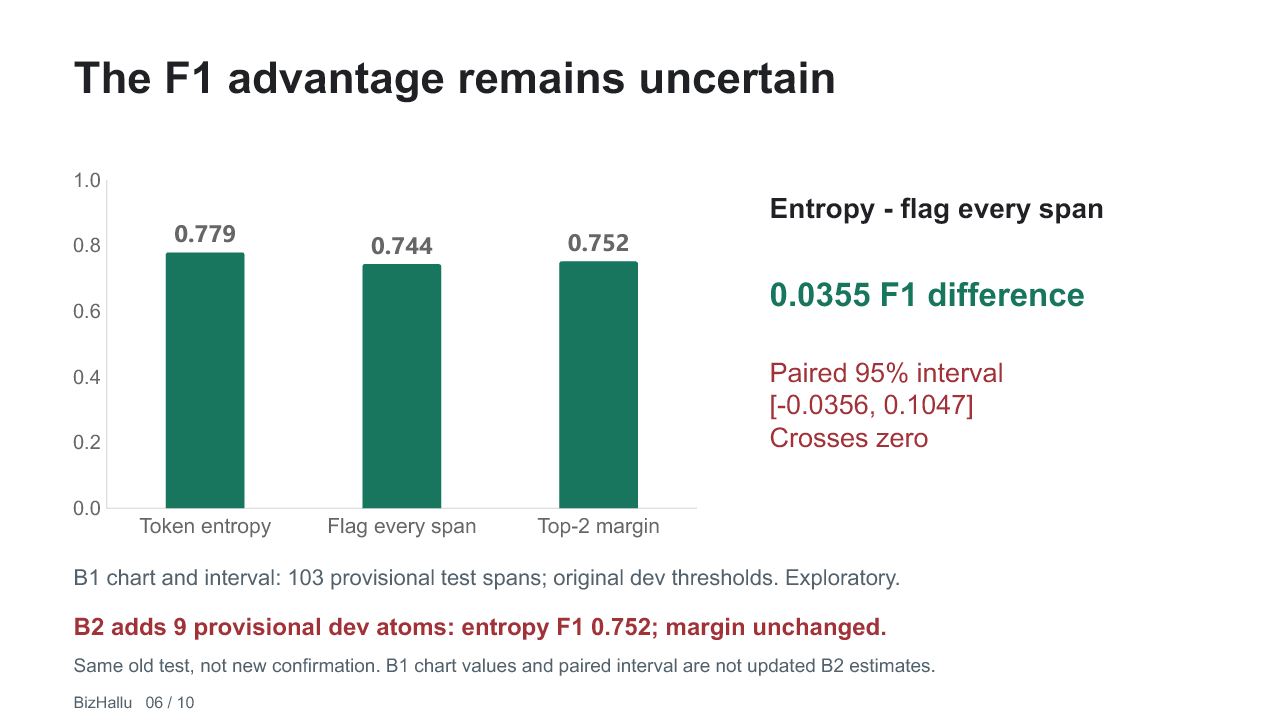
The cases demonstrate a distinction between copying a value correctly and stating a correct relationship. The exploratory detector results do not establish stable superiority over simple references. Entropy F1 is 0.779 versus 0.744 for flagging every span in B1; its paired difference interval crosses zero. The separate B2 dev-omission check changes entropy F1 to 0.752 on the same old test.
Read the statistical interpretation or inspect the B2 sensitivity.
103 test spans from 18 questions, with AI-assisted provisional labels. AP is tied-score-aware average precision, not trapezoidal PR area. Scores use saved-trace precision; historical files are unchanged.
| Signal / reference | AP | F1 | Balanced accuracy | MCC |
|---|---|---|---|---|
| Top-2 margin | 0.835 | 0.752 | 0.753 | 0.498 |
| Token entropy | 0.809 | 0.779 | 0.673 | 0.381 |
| Flag every span | 0.592 | 0.744 | 0.500 | 0.000 |
| Flag no spans | 0.592 | 0.000 | 0.500 | 0.000 |
| Dev fact-type prior (composition control) | 0.760 | 0.836 | 0.714 | 0.555 |
Entropy minus flag-every-span F1: +0.0355; exploratory paired question-bootstrap 95% interval [-0.0356, 0.1047]. This interval crosses zero; it is conditional on fixed dev thresholds and provisional labels, not adjusted for test-based signal selection or all shared-period dependence.
The fact-type prior is an annotation-composition control, not an information-matched detector: supplied type names can contain correctness hints. Its higher F1 is not a new headline result. The two overlapping-period components are too few for reliable cluster inference.
Same-step selected energy gap equals token NLL. Probability outside the top two choices is a concentration control, not an independent replication of Spilled Energy. No superiority claim follows from the historical 0.835 / 0.779 maxima.
September 5 update. B2 sensitivity adds 9 assistant-provisional q_0048 dev atoms. Dev-only refitting changes entropy F1 from 0.779 to 0.752 on the same 103 old test spans; top-2 margin is unchanged. Original B1 results remain intact. This is not fresh held-out evidence or independent review. B2 methods appendix.
Positive and negative transaction values are sign-based accounting quantities. Negative value is not a verified measure of physical returns; fees and adjustments may be included. Merchandise scope uses a stock-code heuristic, and the historical product grain is stock code plus description.
The project motivates controls for revenue summaries and product prioritization; it does not demonstrate realized savings, profit improvement, physical-return rates or inventory optimization. The business risk lens explains the transaction-value reconciliation and accounting boundaries.
Start with Cases, Methods and Research for the current explanation. The supporting materials below provide business context and preserve earlier study records; preparation and assistant review do not establish independent validation.
The 48-context / 96-question next study is estimation-focused and has not been executed. Confirmation remains sealed. The v1.1 business-definition amendment retains the original contexts and splits; preparation is not an outcome.